Sandbot
Lab Assistant
An Azure RAG assistant for a testing lab's technical archive. It answers questions about standards and test procedures with grounded, cited sources instead of guesses.
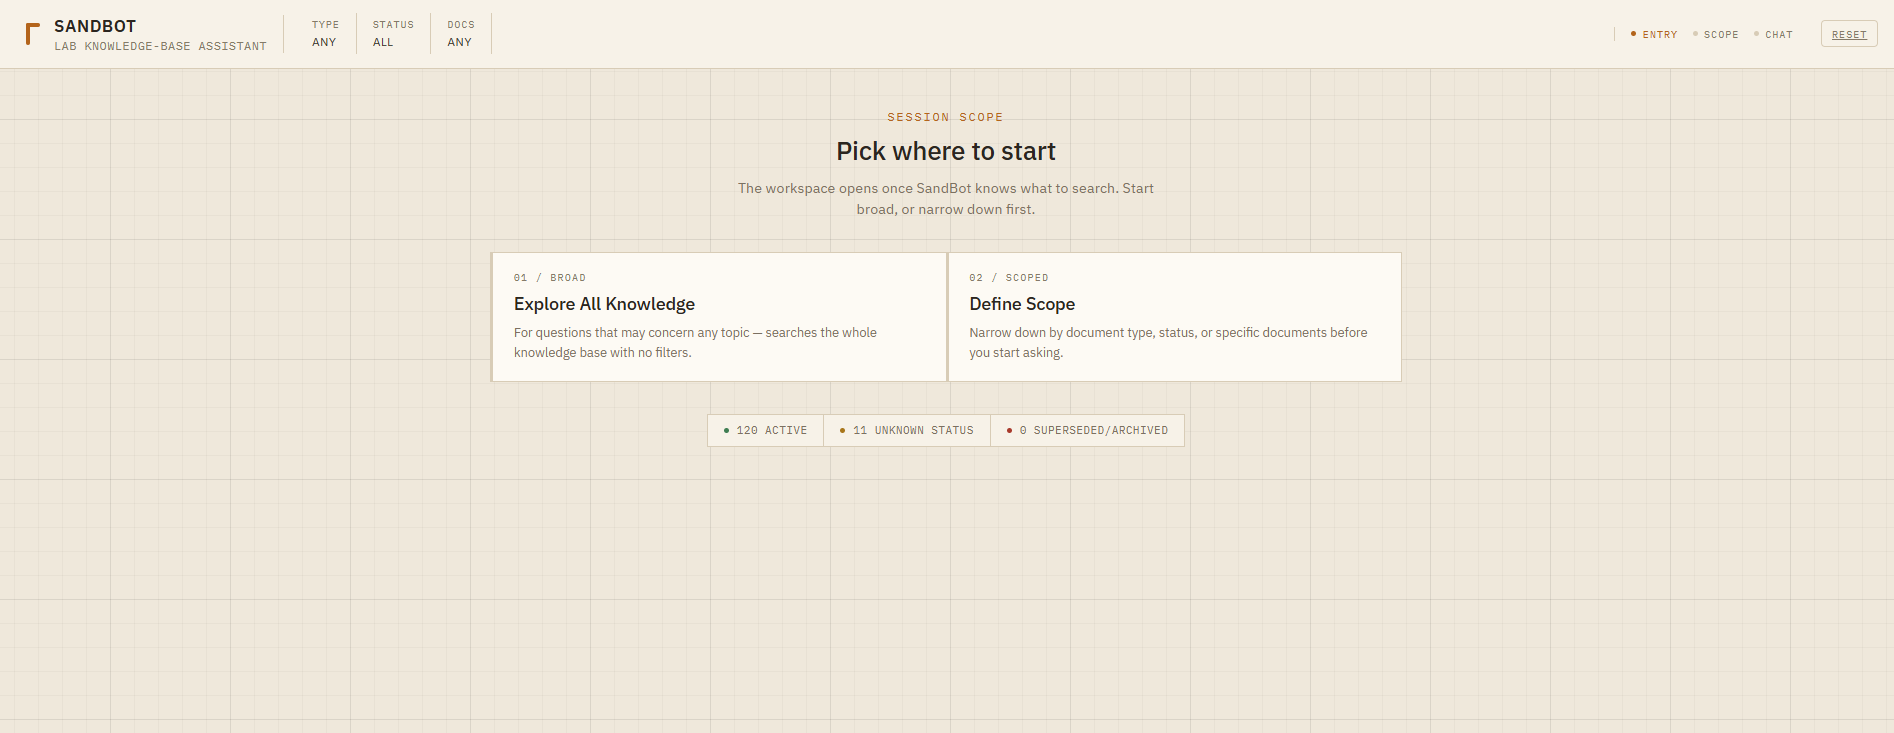
Answers with citations, not guesses.
A testing lab's technical archive covers safety standards, test instructions, historical test reports going back years, and equipment manuals. Finding the current, correct answer among all of it takes real domain memory, and the wrong document can look just as convincing as the right one.
Sandbot treats the archive itself as the source of truth. Every document is broken into structure-aware chunks, embedded, and indexed. The chat model never answers from memory. It only ever answers from chunks it actually retrieved, and every answer names the exact chunks behind it.
Standards, test instructions, and years of test reports sit across many documents. Finding the current, correct answer takes real domain memory.
Documents are chunked, embedded, and indexed in Azure AI Search. The chat model only answers from chunks it actually retrieved.
A working tool that answers real lab questions with cited sources, verified end to end against real Azure resources.
From raw documents to searchable chunks
Every document goes through the same local pipeline before it ever reaches Azure. A checksum-based registry tracks what's changed so nothing gets reprocessed twice. Source-specific extractors pull clean text out of DOCX and PDF files. A structure-aware chunker splits each document by section and heading instead of by a fixed word count, so a chunk never cuts a procedure in half. Schema validation runs against the real output, not just example data, and it already caught two real extraction bugs before they reached the index.
Retrieval that can't wander outside its sources
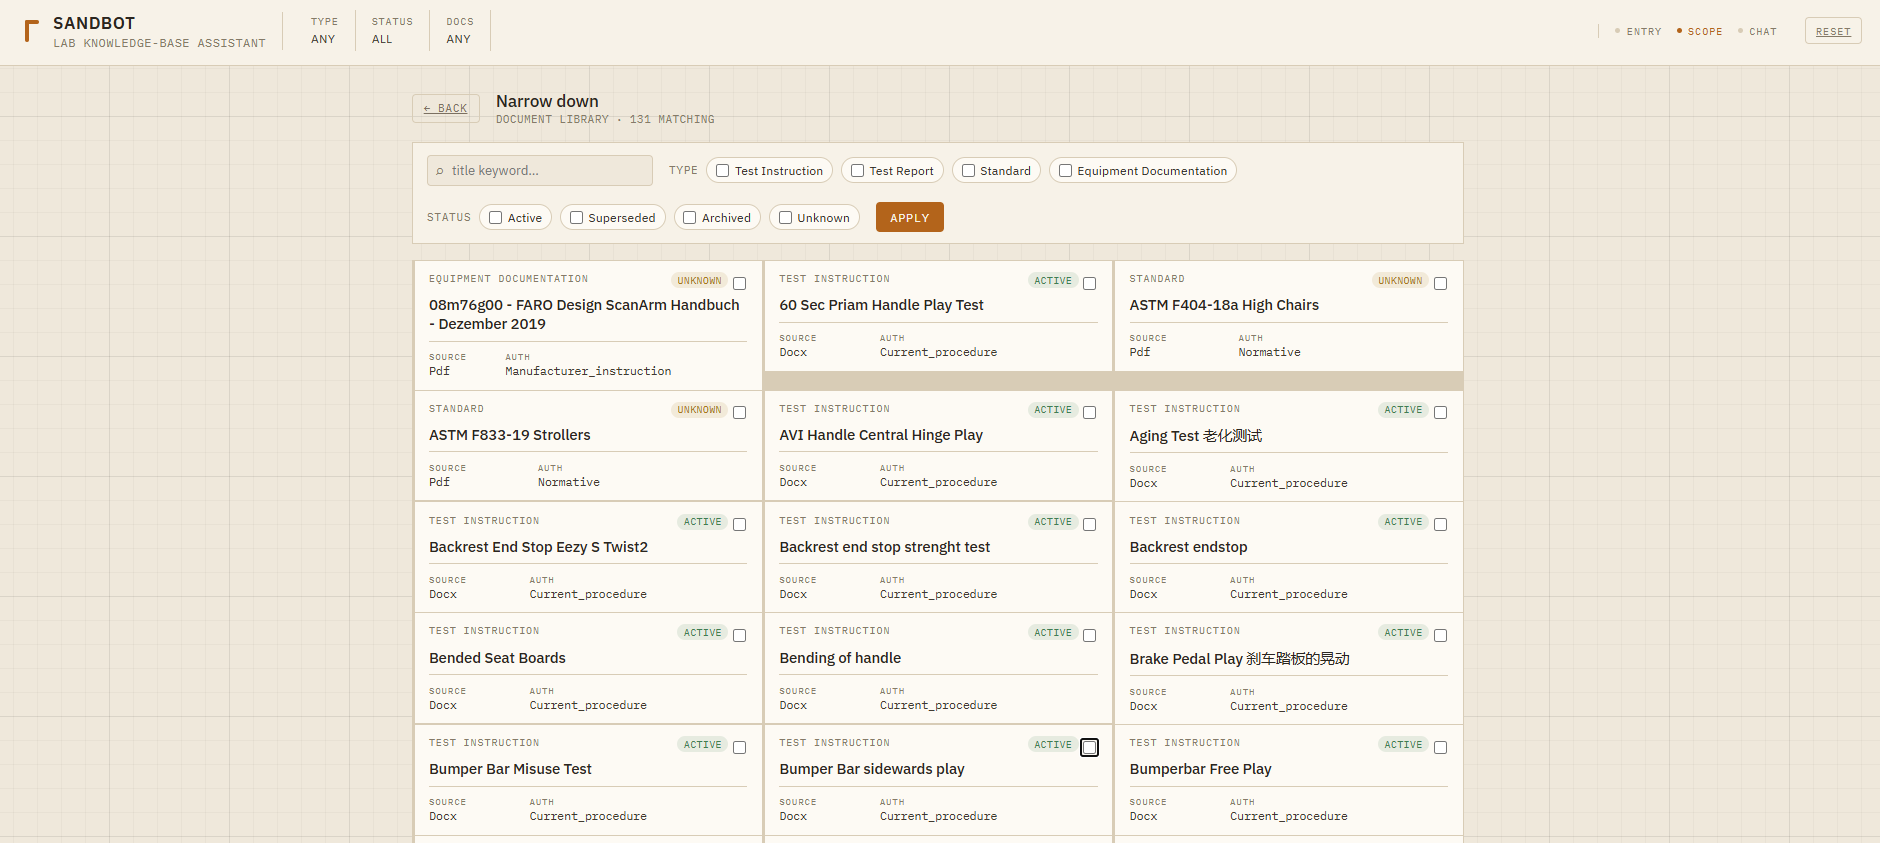
Each question triggers a hybrid search. Keyword matching and vector similarity run together against Azure AI Search, and an optional scope filter can narrow that search to one document or category first. That filtering happens inside Search itself, not as an instruction to the chat model, so anything outside the chosen scope never reaches it. The model answers only from what it retrieved, in structured JSON with the exact chunk IDs it relied on, so every citation points back to a real passage instead of a guess.
Checksum change detection
Structure-aware chunking
Azure AI Search (HNSW)
Structured, cited answers
Chunks Are the Knowledge Base
The chat model isn't the source of knowledge. The indexed chunks are. The model's job is turning retrieved chunks into a readable answer, nothing more.
Local-First Processing
Extraction, normalization, chunking, and validation all run locally. Azure only ever sees clean, finished chunks.
Scope Enforced in Search
Document and category filters run inside Azure AI Search itself, not as a prompt instruction the model could ignore.
Structured Citations
Every answer returns as JSON with the exact chunk IDs behind it, so citations are exact, not parsed out of prose.
Entra ID, No API Keys
Every Azure call authenticates through Microsoft Entra ID. There's no API key sitting in a config file to leak.
Cost-Aware By Default
Any cost-incurring call, embeddings, indexing, chat completions, needs a stated scale estimate and explicit approval first.
This isn't a finished product yet. Here's what's actually proven, and what still isn't.
A working tool answers real questions from the lab's archive end to end, from a typed question to a grounded answer with a citation. It runs against real Azure resources, not a mock, and the ingestion pipeline has been verified against real documents, not just example data.
Retrieval quality hasn't been formally evaluated yet. Forty-two documents that are image-only, and unreadable by text extraction, are excluded from the index for now. The assistant hasn't been deployed anywhere beyond a local development server.